· via Hacker News – Front Page (native)
Google open-sources vectorized Quicksort with up to 19x speedup over std::sort
Google has released an Apache 2.0 vectorized Quicksort that sorts roughly ten times faster than C++ std::sort while staying portable across x86, Arm and RISC-V instruction sets.
A portable sort that runs at memory-bus speeds
Google has published an open-source, vectorized Quicksort that it says sorts arrays of numbers around ten times faster than the C++ standard library's std::sort, while remaining portable across modern CPU architectures. According to the post on the Google Open Source Blog, written by Jan Wassenberg of the company's Brain Computer Architecture Research group, the code beats existing architecture-specific sorts on some hardware and is available under an Apache 2.0 license on GitHub. The post resurfaced on the Hacker News front page this week.
The work was motivated by the shift toward columnar databases, which store all values from a single column contiguously rather than grouping all fields of a record together. As the blog explains, this layout makes filtering and sorting — two fundamental operations in SQL query execution — considerably cheaper, and it is the data layout the new sort targets.
Where the speedup comes from
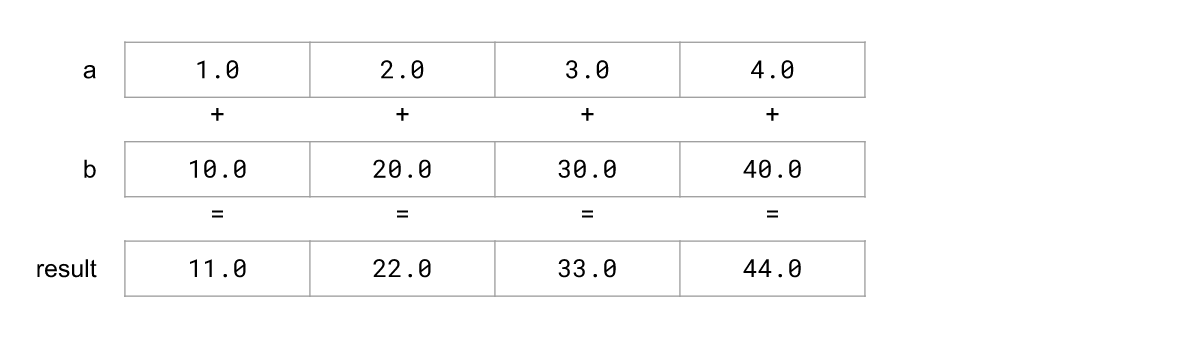
Sorting has been studied for decades, so a large gain has to come from hardware rather than a new algorithm. The key is SIMD (single instruction, multiple data), which applies one instruction to several independent values at once — for example, 16 float32 values per instruction on AVX-512, or four on Arm NEON.
The obstacle is that SIMD works on independent elements, whereas sorting rearranges neighbouring ones. The solution described by Wassenberg is to concentrate the vectorization in the partitioning step of Quicksort, which consumes most of the CPU time in the algorithm. The array is repeatedly split around a pivot value into elements below and above it, until a sub-array is small enough — 256 elements in this implementation — to be handled by a dedicated routine documented in the accompanying paper.
Modern instruction sets such as x86 AVX-512, Arm SVE and RISC-V V include a compress-store instruction that is a natural fit: given a mask of yes/no flags marking which elements are smaller than the pivot, it writes only the flagged elements into consecutive memory. Negating the mask and repeating the operation writes out the other partition. On instruction sets that lack compress-store, notably AVX2, the blog notes that prior research showed how to emulate it using permute instructions.
One implementation, six instruction sets
Earlier vectorized sorts were written for one specific instruction set. This project, built on Google's Highway portable-SIMD library, is described as the first vectorized Quicksort that works across six instruction sets spanning three architectures, without rewriting roughly 3,000 lines of C++ for each platform. Highway selects compress-store where it exists and falls back to permute-based emulation otherwise, choosing the best available path at runtime.
The implementation also widens the input range: where the previous state of the art handled only 32-bit integers, the new sort supports 16- to 128-bit inputs.
The benchmark numbers
According to the blog post, sorting one million 32-, 64- or 128-bit numbers on an Apple M1 (Arm NEON) reaches throughput of 499, 471 and 466 MB/s respectively. On a 3 GHz Intel Skylake with AVX-512, the figures rise to roughly 1,120 MB/s across all three widths. On AVX2 hardware the new code measures 798 MB/s, ahead of the 699 MB/s of the prior AVX2-optimized state of the art.
The comparison with the standard library is the headline: on the same CPU, std::sort manages 58, 128 and 117 MB/s for the three widths, putting the speedup at 9x to 19x depending on the numeric type. The blog also notes that AVX-512 runs 1.4–1.6 times faster than AVX-2 with no code changes, since Highway detects what the CPU supports.
Why it matters
Sorting has traditionally been treated as a relatively expensive operation, and the post argues that being able to sort at roughly 1 GB/s on a single CPU core could unlock applications and capabilities that were previously impractical — an appealing prospect for columnar database engines and data-processing pipelines generally.
For developers, there are two practical takeaways. First, the sort itself is available now under a permissive license, with the authors inviting questions and issues on GitHub. Second, it is a concrete demonstration of what portable SIMD abstraction layers like Highway can achieve: performance that previously required hand-written, per-architecture code, delivered from a single codebase that automatically adapts to whatever vector instructions the host CPU offers.
- #open-source
- #simd
- #c-plus-plus
- #performance
- #sorting
- #algorithms